Exhibit 6.5
5Alignment
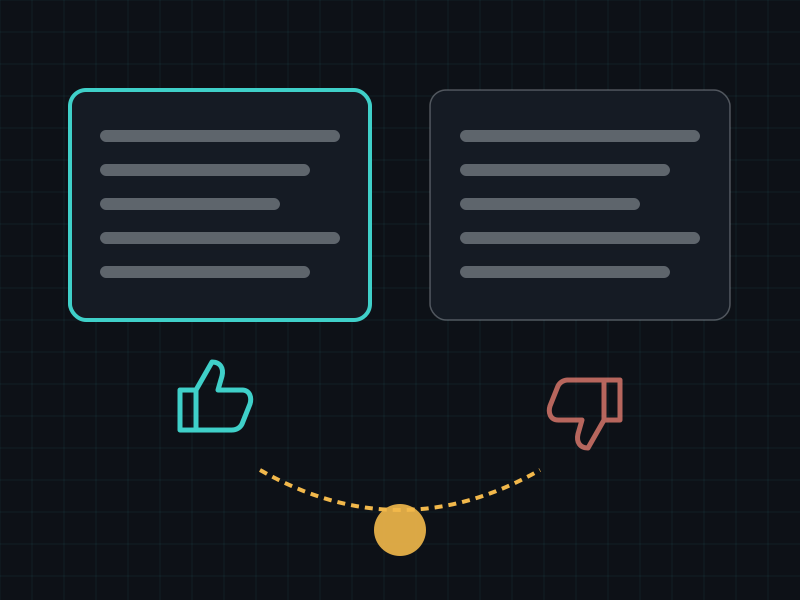
People, and sometimes other models, evaluate answers. Training then pushes the model toward responses judged more helpful, honest or safe. A well-known approach is reinforcement learning from human feedback (RLHF).
Why it is in the museum
A modern language model does not appear fully formed. It passes through data collection, training, adaptation, evaluation and, finally, answer generation.
What supports this exhibit
Primary research paper
The use of human preferences and reinforcement learning to shape model behaviour.
Main source: Ouyang, L. et al. (2022), “Training language models to follow instructions with human feedback”.
What to keep in mind: Primary source; modern systems also use methods beyond RLHF.
Ask the exhibit
This small guide uses only the information documented on this exhibit page. If your question goes beyond that evidence, it will say so instead of inventing an answer.
Start with one of the suggested questions above, or type your own.