Exhibit 6.2
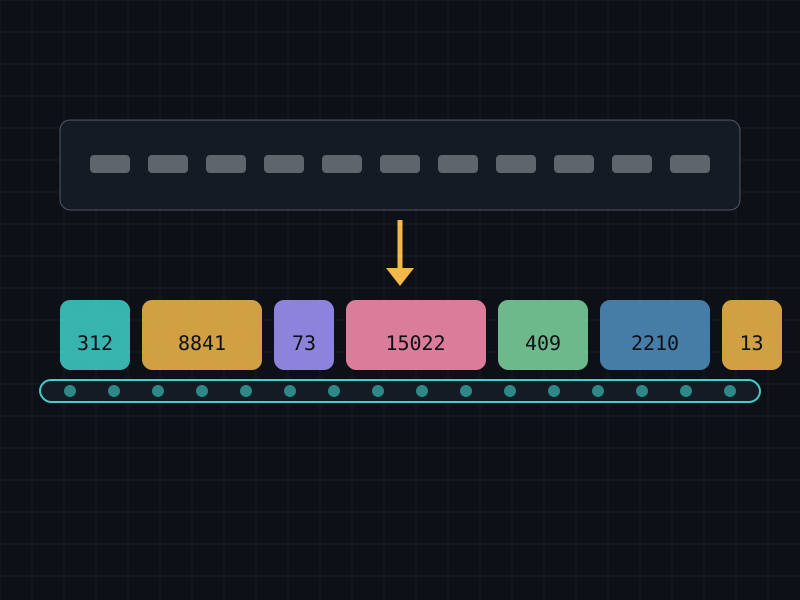
2Tokenization
Text is split into smaller units called tokens, which may be whole words or pieces of words. The model processes numerical identifiers rather than written characters directly.
Why it is in the museum
A modern language model does not appear fully formed. It passes through data collection, training, adaptation, evaluation and, finally, answer generation.
What supports this exhibit
Primary research paper
The use of subword units such as BPE to represent rare or previously unseen words.
Main source: Sennrich, Haddow & Birch (2016), ACL, subword units.
What to keep in mind: Primary source; exact tokenizers differ across models.
Ask the exhibit
This small guide uses only the information documented on this exhibit page. If your question goes beyond that evidence, it will say so instead of inventing an answer.
Start with one of the suggested questions above, or type your own.